
Google Cloud lets BigQuery query Databricks, Snowflake
Tue, 27th Oct 2026 (Today)
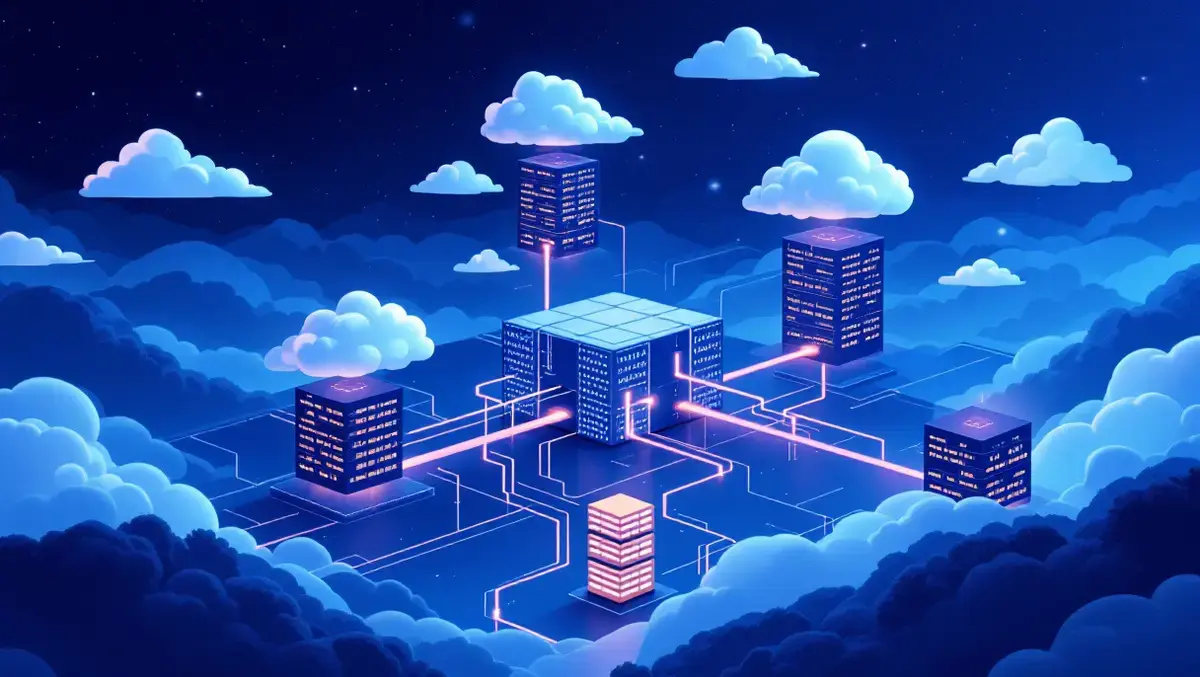
Google Cloud has outlined a way for BigQuery to query data stored across Databricks, Snowflake and AWS Glue without moving the underlying datasets. The approach uses federated Apache Iceberg REST catalog connections in Google Cloud.
The setup is aimed at organisations whose data is spread across multiple clouds and operational systems, a pattern that often leaves analytics teams choosing between building pipelines into a central warehouse and working with inconsistent reporting.
Under the model Google Cloud described, BigQuery can synchronise metadata from external catalogues while reading Parquet data files directly from remote object storage at query time. Query processing runs on Google Cloud compute, while remote Databricks clusters, Snowflake virtual warehouses and AWS compute instances are not used during execution.
The architecture separates metadata synchronisation from storage access. Lakehouse runtime catalog periodically syncs schemas, snapshot pointers and table definitions from remote catalogues on a user-defined refresh schedule, while direct storage access uses temporary credentials issued by the external platform.
How It Works
The example configuration linked BigQuery to Databricks Unity Catalog, Snowflake Horizon Catalog and AWS Glue Data Catalog, all of which support the Apache Iceberg REST catalog specification. That shared support allows a common connection pattern across the three platforms.
In the Databricks example, a schema was associated with an external location and an Iceberg table was created for product data. A Databricks service principal was then used to establish the federated connection in Google Cloud, with permissions granted for catalog traversal, schema use and data access.
For Snowflake, Google Cloud described creating an Iceberg table for customer data, assigning a dedicated reader role and binding Google Cloud's numeric identity to a service user through Workload Identity Federation. In AWS, the process involved creating an IAM role, attaching permissions for AWS Glue and Amazon S3, and then registering an Iceberg table through Amazon Athena.
Single Query
Google Cloud showed how a single SQL query could join native BigQuery sales data with customer records held in Snowflake, product information stored in Databricks and store location data kept in AWS Glue. In the example, BigQuery used four-part table paths to reference federated Iceberg tables across the three external catalogues.
The query grouped sales by customer, product and store, then ranked the results by total sales revenue. Snowflake identifiers appear in uppercase in this setup, while Databricks and AWS Glue paths remain in lowercase.
Google Cloud also described saving the multi-cloud join as a logical view in BigQuery so users could query the combined dataset through conversational analytics. In the example, a user could ask a natural language question about top customers, the products they bought and the stores they used, with BigQuery generating and running the SQL against the federated sources.
Operational Limits
The minimum metadata refresh interval for the federated catalogues is 300 seconds. For larger catalogues with hundreds of tables, metadata retrieval can take longer. If one synchronisation cycle overruns, the next scheduled run is skipped to avoid queueing tasks.
BigQuery also caches retrieved cross-cloud data blocks in the region where the federated catalogue resides. That can reduce network transfer for repeat queries, but it also raises data residency considerations because the cached blocks sit in Google Cloud storage in that region.
Where organisations enforce the constraints/gcp.restrictNonCmekServices policy constraint, BigQuery bypasses the cache and reads directly from remote storage for each query. Users can monitor cache use through the objectStorageStats section in BigQuery job statistics by comparing cacheBytesRead with objectStorageBytesRead.
The design addresses a common problem in multi-cloud analytics. Traditional extraction pipelines can introduce synchronisation lag, storage overhead and network egress charges. Upstream schema changes can also break pipelines and create mismatched metrics across dashboards.
Google Cloud presented the federated model as an alternative in which compute is brought to the data rather than data being copied into a central store. Cross-cloud metadata synchronisation and direct reads from remote storage form the basis of the approach.